Do Your Qlik Apps Keep Creating Synthetic Keys?
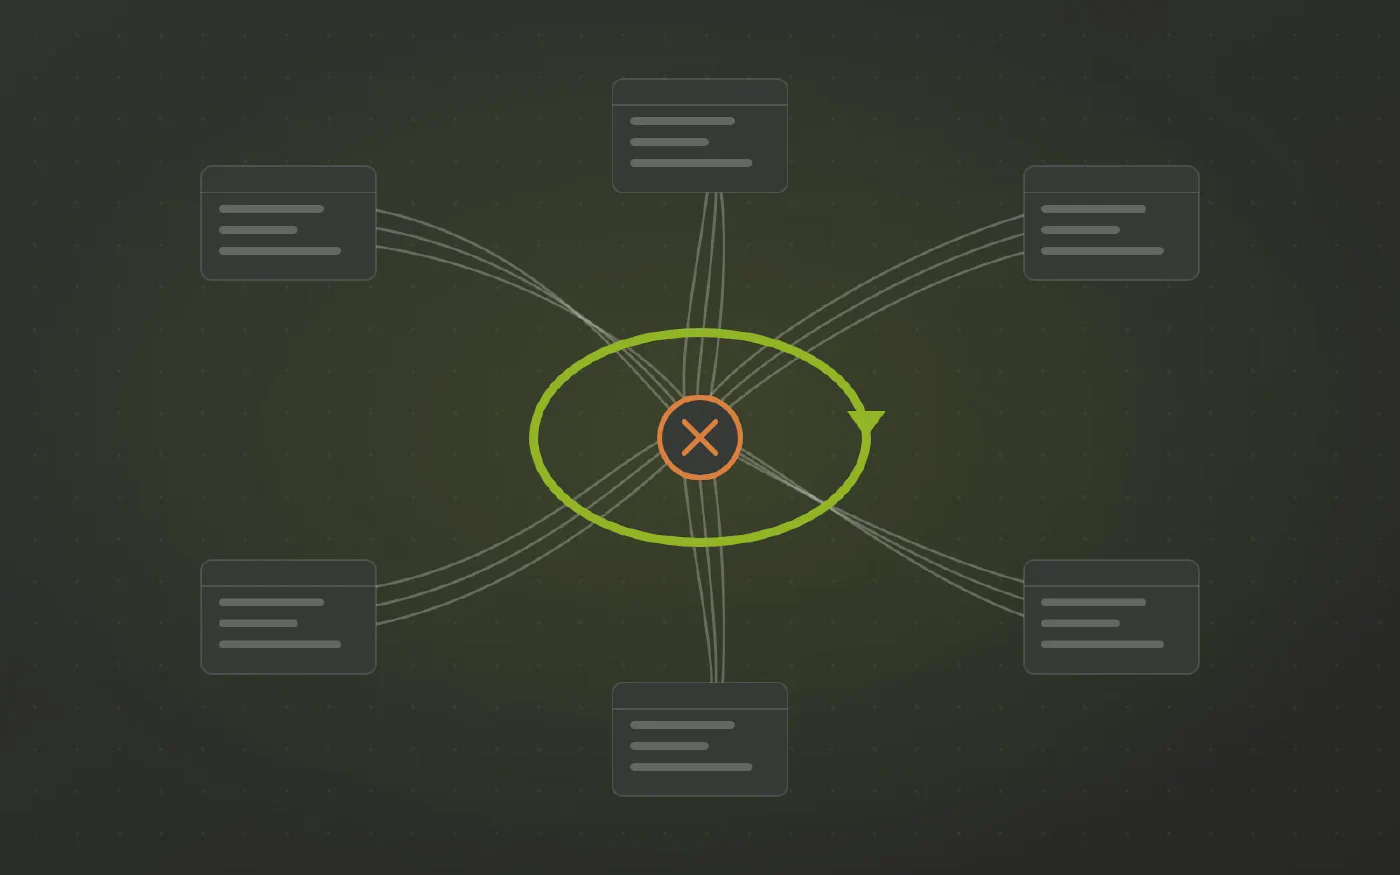
Synthetic keys and circular references are Qlik associating exactly what it was given. They appear because the data arrives without conformed dimensions or real keys, so every app has to invent them.
The data warehouse automation platform trusted by data teams across industries
Does this sound familiar?
- The data model viewer is full of $Syn tables nobody meant to create.
- A reload warns about a circular reference and one table ends up loosely coupled.
- The top of every load script is a block of renames, QUALIFY statements and link tables.
- Adding one new table to an app breaks associations that worked yesterday.
A synthetic key is Qlik doing exactly what it should with the tables it was handed. When several tables share several field names, the engine has to associate them somehow.
What the synthetic keys are telling you
- Several tables share several fields. Qlik builds a
$Syntable for each combination, and the model viewer fills up with them. - Two routes lead to the same table. That is a circular reference, and Qlik loosely couples a table to break the loop.
- The fixes are structural. Link tables, concatenated facts,
QUALIFY, renaming withAS, composite keys built withAutoNumber. - Each fix is local. It resolves this app, and the next app on the same sources starts again.
Each one is a key that should have existed before the data reached Qlik.
Why it lands on you
- The extracts arrived with whatever field names each source system happened to use.
- Nobody upstream decided which
CustomerIDis the customer, so the load script has to. - You can rename a field in Qlik. You cannot conform the dimension it came from.
The work is in the wrong place
- Deciding how tables relate is warehouse work. In Qlik it is redone in the load script of every app.
- It belongs in one central place: a data warehouse or data hub, built once and read by every app.
- If that sounds expensive, the estimate probably assumes hand built pipelines. A specialised automation platform generates them from a model, which changes both the cost and the time it takes.
What changes when the model arrives finished
Datavault Builder generates the vault and the dimensional layer natively in the database you already have, whether that is Snowflake, Databricks, SQL Server, Fabric, Oracle or PostgreSQL.
- Conformed dimensions mean one customer table and one customer key, shared by every fact.
- Surrogate keys join on a single field, so there is nothing left for Qlik to synthesise.
- Facts at a declared grain replace the link table you were maintaining by hand.
- The load script becomes a plain
LOADfrom finished tables, with no rename block on top. - A new app starts from the model, not from a copy of the last fix.
What to ask for
Not “Qlik keeps creating synthetic keys”, but:
“Our apps need link tables and renamed fields because orders, invoices and shipments each carry their own customer and date keys. Can the warehouse deliver conformed dimensions with surrogate keys, so every app loads the same star schema?”
If the reply is that conforming those dimensions would take a quarter of engineering time, that is exactly the objection Datavault Builder removes.
See It Working on Your Own Data
Book a free demo and bring the report that gives you the most trouble.
Three Steps to Numbers That Add Up
-
Extract the existing logic
Collect the calculations, joins and filters that live in your reports today.
-
Centralize it in one place
The logic moves into the warehouse model once, so every report reads the same definition.
-
Enjoy numbers that add up
Every report shows the same figure, and “where did this number come from” has a visible answer.
How Datavault Builder Hands Your Report a Finished Model
-
The model arrives finished
Datavault Builder generates the vault and the star schema to run natively in the database you already have: SQL Server, Azure SQL, Synapse, Fabric, Snowflake, Databricks or BigQuery.
-
The work leaves the report
No merge, no parsing, no fuzzy match. That work is gone from the report.
-
Sources arrive integrated
Customers from the ERP, the CRM and the web shop are matched into one set of conformed dimensions. The join happens once in the warehouse, not again in every report.
-
History you can query
Every change is retained as it arrives, so you can report as-was as well as as-is, even where the source system overwrites its own records.
-
Every number has lineage
The logic gains lineage, so “where did this number come from” has a visible answer.
-
Changes handled upstream
Slowly changing dimensions are handled upstream as vault satellites, not approximated.
Recognized by BARC in The Data Fabric Survey 26
Meet Our Expert
Twenty minutes with our Sales Director, and an honest answer on whether this fits your situation.
Matt Collett
Sales Director
Great, pick a time that works for you:
Other Problems This Series Covers
-
Do Your Qlik Apps and Power BI Reports Show Different Numbers?
Neither Qlik nor Power BI is wrong. Each has its own load logic, its own definitions and its own lineage, so the same metric is calculated twice and nobody can reconcile them. The rules belong in one governed warehouse model both tools read.
-
Do You Clean the Same Data Again in Every Qlik Load Script?
The same mapping loads, string fixes and deduplication are written again in every app and QVD layer, and the copies drift apart. The cleansing is repeated per script because no integrated warehouse layer does it once.
-
Are Your Qlik Set Analysis Expressions Too Long and Too Slow?
Set analysis is precise for genuine comparisons. Most of the long expressions in your app are there because the model never delivered history, flags or a single grain, so the chart rebuilds them on every selection.